The short answer
Small trials can be valuable early evidence, but they produce wider uncertainty, are more vulnerable to baseline imbalances and dropout, detect harms poorly, and can exaggerate effects when only striking positive findings receive attention. Buyers are often shown one favorable number without the comparison group, absolute size, confidence interval, duration, exact tested formula, adverse events, or funding context. Those missing pieces can completely change what the result means.
With few participants, chance has more room to create unusually large benefits or uneven groups. A result can cross the significance threshold only because the observed effect is extreme. Later, larger studies often estimate a smaller effect or none at all.
Start with the research question
Every study is built to answer a limited question. Identify the population, intervention, comparator, outcome, and time frame before reading the conclusion. A trial in young healthy adults may not answer a claim aimed at older adults with obesity. One dose cannot establish months of benefit, and a laboratory surrogate cannot substitute for measured weight or body composition.
Next separate discovery from confirmation. Exploratory research can identify a signal worth testing. Confirmation requires a suitable control, adequate size, prespecified outcomes, transparent analysis, replication, and results relevant to the marketed claim.
A five-question buyer checklist
- Was sample size justified before recruitment?
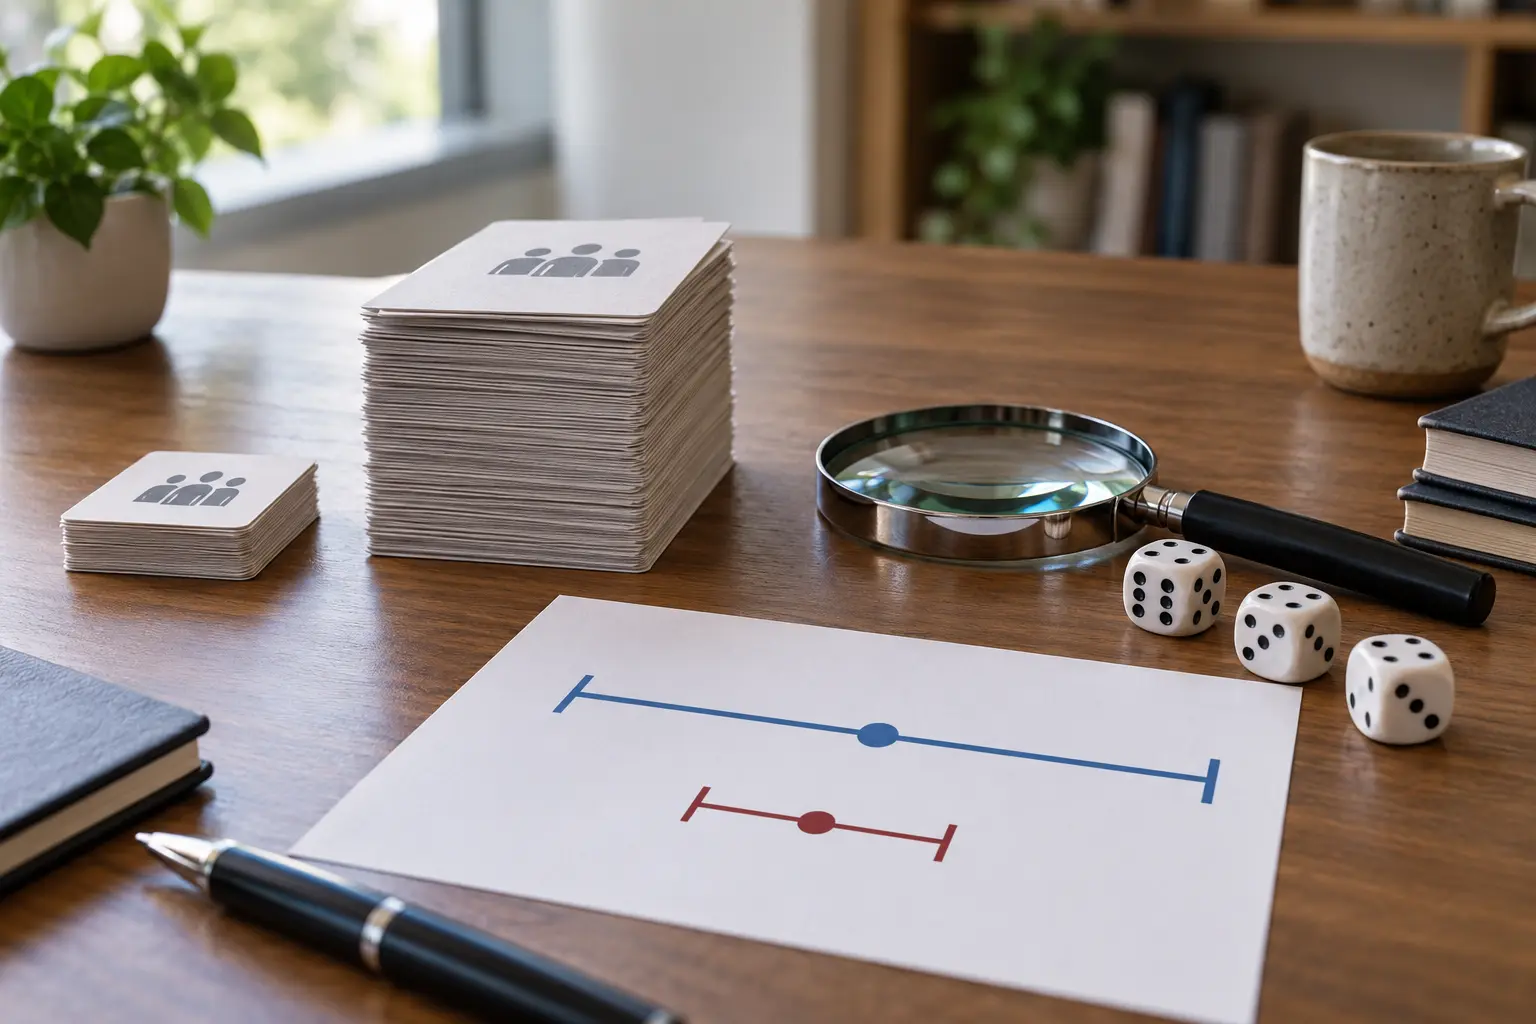
- How wide is the confidence interval around the effect?
- Were groups balanced at baseline and were analyses adjusted transparently?
- How many participants dropped out, and why?
- Was the result replicated by an independent, adequately powered study?
If the paper or marketing page does not provide enough information, do not fill the gaps with optimistic assumptions. “More research is needed” is not proof that the product works; it is a statement about uncertainty.
Read the numbers in the right order
Begin with the between-group absolute difference. Then read the confidence interval, which shows a range of effects reasonably compatible with the data under the model. A p-value does not report effect size, practical importance, certainty of replication, or the probability that the marketing claim is true.
Check baseline values and the number actually analyzed. Percent changes can look large when starting values are small. Per-protocol analyses may exclude people who stopped using the product, while intention-to-treat analyses better preserve the original randomized comparison when handled appropriately.
Worked example
A 20-person trial reports three kilograms more loss with a supplement, but the confidence interval is wide and four participants leave the placebo group. The finding is a reason for a larger preregistered trial, not a reliable forecast for buyers.
A sound conclusion uses the narrowest wording supported by the design. It does not turn a mechanism into weight loss, an ingredient into a formula, a within-group change into superiority, or statistical significance into a benefit buyers will notice.
Bias and reporting signals
Look for trial registration, a prespecified primary outcome, funding and conflicts, randomization methods, allocation concealment, blinding, adherence, dropout, adverse-event reporting, and access to the protocol. Industry funding does not automatically invalidate a trial, but it increases the importance of transparent methods and independent replication.
Multiple outcomes and time points create many chances to find one favorable result. If the abstract emphasizes a secondary outcome while the registered primary outcome was null, caution is appropriate. Selective publication can also make the visible literature look more positive than all completed research.
Build an evidence ladder
- Mechanism: biologically plausible, but not an outcome.
- Acute human response: shows a short signal under controlled conditions.
- Ingredient trial: tests a defined substance, dose, population, and period.
- Finished-product trial: tests the formula buyers receive.
- Independent replication: asks whether the result survives another team and sample.
- Systematic review: examines the total evidence, heterogeneity, and bias.
Higher steps do not rescue a mismatch. A review of a different dose, extract, population, or outcome may still be weak support for a specific product claim.
A practical decision rule
Classify the claim as supported, promising but uncertain, unsupported, or contradicted. “Supported” requires direct, relevant, sufficiently precise evidence and a meaningful effect. “Promising” means the signal justifies more research, not a confident purchase claim. “Unsupported” means evidence is missing or too indirect.
Before buying, ask what decision would change if the true effect were at the lower end of the confidence interval. If that outcome would not justify the price, inconvenience, stimulant exposure, or risk, the headline estimate is not enough.
Use the result with related checks
Apply the same distinctions in our guides to mechanism versus measurable outcome, realistic fat-burner effects, and why exact ingredient amounts matter. Together they prevent a plausible story from being mistaken for product-level proof.
Where Fat Burn Active fits
Fat Burn Active is relevant to Why Small Supplement Studies Need Caution because its official listing identifies standardized plant extracts, caffeine sources, vitamins, and zinc in one formula. First read our independent review. If the formula, stimulant profile, evidence limits, and warnings fit your situation, check the current formula and purchase options on the official Fat Burn Active website. We may receive a commission at no additional cost.
What a small trial can tell you
Small studies help with feasibility and early observations, but an average can move substantially when a few participants change outcome. Imagine a trial with twelve people per group and one unusually large weight change in the supplement group. That person's result can pull the group average upward. A confidence interval communicates this uncertainty better than a single percentage. If it includes both negligible benefit and a worthwhile effect, the study has not settled the buying question.
Check the number randomized, the number who finished, and the number included in the primary analysis. Losing three participants from a group of twelve is a quarter of that group. Ask why they left and whether side effects or lack of benefit could be involved. Also compare baseline characteristics: randomization does not guarantee that small groups begin with the same weight, sleep, medication use, or diet. A large apparent effect can be partly a starting imbalance rather than a reliable treatment response.
Safety claims are especially fragile in a small, short study. The absence of a reported adverse event among a few dozen people does not establish safety for thousands of consumers, longer use, pregnant people, or those taking medicines. Trials may exclude precisely the people most likely to have problems. Read the exclusions, dose, follow-up, and adverse-event collection method before calling a product “well tolerated.” A supplement containing several stimulants also needs its combined exposure assessed, not simply a list of individually familiar ingredients.
One striking positive paper should prompt a search for registered but unpublished studies, independent replications, and systematic reviews of comparable interventions. Look for the same outcome, dose, population, and duration; pooling unlike studies does not erase the mismatch. If the evidence remains one small trial, describe it as preliminary even when its p-value is below a conventional cutoff. A practical purchase decision can then account for uncertain benefit, known costs, and personal risk without pretending the early signal is a confirmed result.
Frequently asked questions
Does statistical significance mean a supplement works?
Not by itself. You still need effect size, uncertainty, relevance, duration, replication, and harms.
Is one randomized trial enough?
It can be important evidence, but one trial may be imprecise, biased, unusually positive, or unlike the marketed product. Independent replication and the total evidence matter.
Can a negative small study prove no effect?
No. A small study may be unable to detect a modest effect. Read its confidence interval to see which benefits and harms remain compatible with the data.
Keep a short evidence note with the tested dose, formula, population, duration, comparator, primary outcome, absolute result, confidence interval, adverse events, funding, and unresolved question. This prevents a later advertisement from replacing the study’s actual limits with a stronger claim.
Sources
- Small-study effects review
- CONSORT reporting guidance
- CONSORT 2025 explanation and elaboration
- New look at P values in randomized trials
- FDA evidence-based review system
- Reporting completeness in nutrition research
Evidence reviewed September 16, 2026. Educational information only; not medical advice.